Hugging Face
Models
Datasets
Spaces
Buckets
new
Docs
Enterprise
Pricing
Website
Tasks
HuggingChat
Collections
Languages
Organizations
Community
Blog
Posts
Daily Papers
Hardware
Learn
Discord
Forum
GitHub
Solutions
Team & Enterprise
Hugging Face PRO
Enterprise Support
Inference Providers
Inference Endpoints
Storage Buckets
Log In
Sign Up
Yi Cui
onekq
24
20
1
Follow
Csplk's profile picture
NoobChanAI's profile picture
Avram1959's profile picture
259 followers
·
30 following
onekq_ai
onekq
yicui
AI & ML interests
Benchmark, Code Generation Model
Recent Activity
posted
an
update
2 days ago
What do you plan to use Muse for?
replied
to
their
post
2 days ago
My takes on Jev 1. Very likely a small model. You can certainly pretrain, but I would grab an existing base model, say Qwen 3 class 2. The new RL method is a breakthrough, classification doesn't need to align with human preferences 3. The new output is an overstatement. It's just a new LM head. Of course autoregressive decoding can be used for classification: it takes just a few tokens to express the output. Think twice: are you sure classification doesn't need few-shot, CoT, or reasoning? All of these depend on auto-regressiveness 4. It carves out a market already existing, which is now served by oversized LLMs (hence overpaid), e.g. LLM as judge, labeling 5. Jevons effect will kick in, promoting more modeling efforts for small budget teams. It might even accelerate RSI
replied
to
their
post
5 days ago
My takes on Jev 1. Very likely a small model. You can certainly pretrain, but I would grab an existing base model, say Qwen 3 class 2. The new RL method is a breakthrough, classification doesn't need to align with human preferences 3. The new output is an overstatement. It's just a new LM head. Of course autoregressive decoding can be used for classification: it takes just a few tokens to express the output. Think twice: are you sure classification doesn't need few-shot, CoT, or reasoning? All of these depend on auto-regressiveness 4. It carves out a market already existing, which is now served by oversized LLMs (hence overpaid), e.g. LLM as judge, labeling 5. Jevons effect will kick in, promoting more modeling efforts for small budget teams. It might even accelerate RSI
View all activity
Organizations
Posts
128
view post
Post
52
What do you plan to use Muse for?
See translation
View all Posts
Articles
8
Article
🔀 Matrices in Transformers: Preface
View all Articles
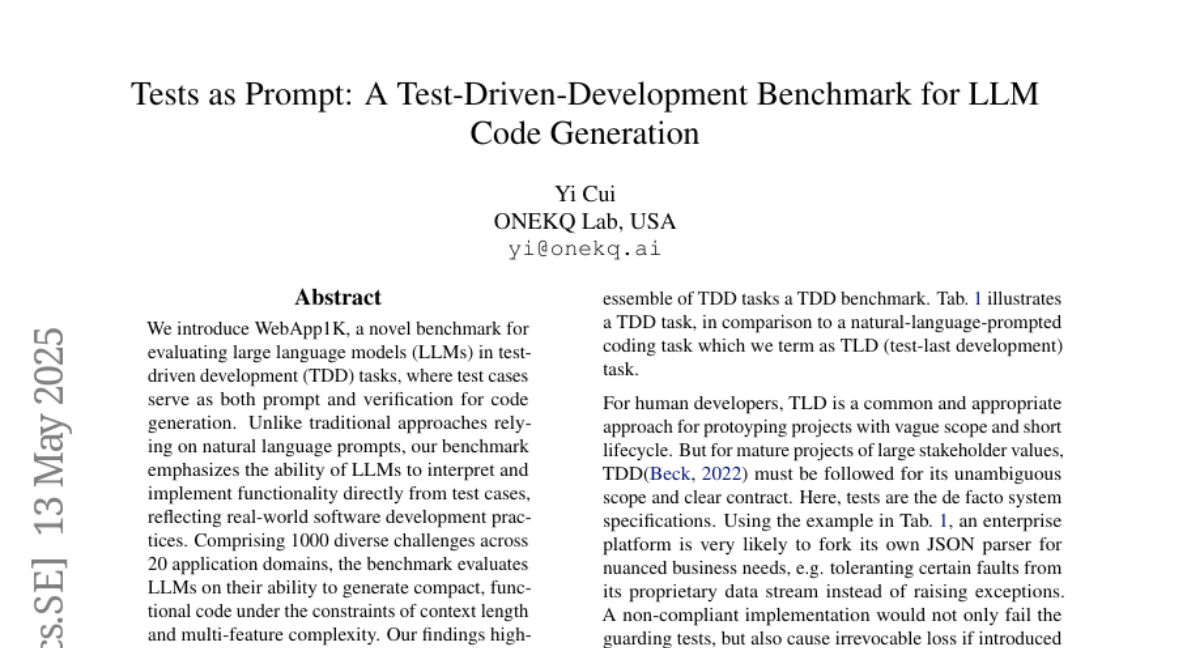
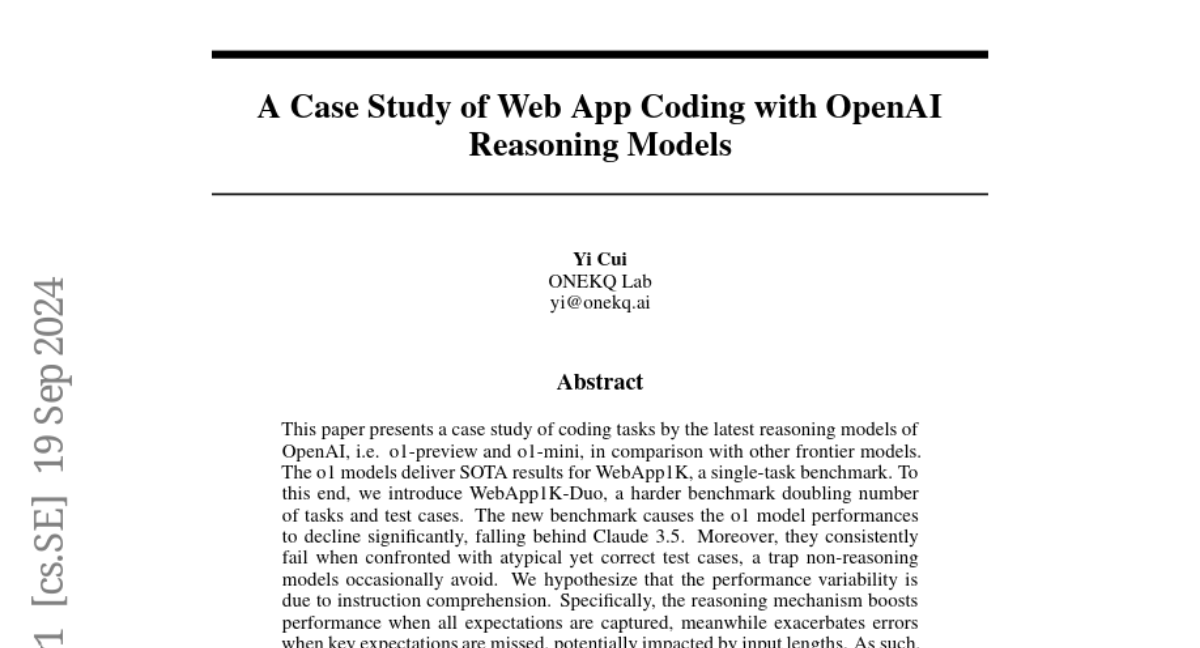
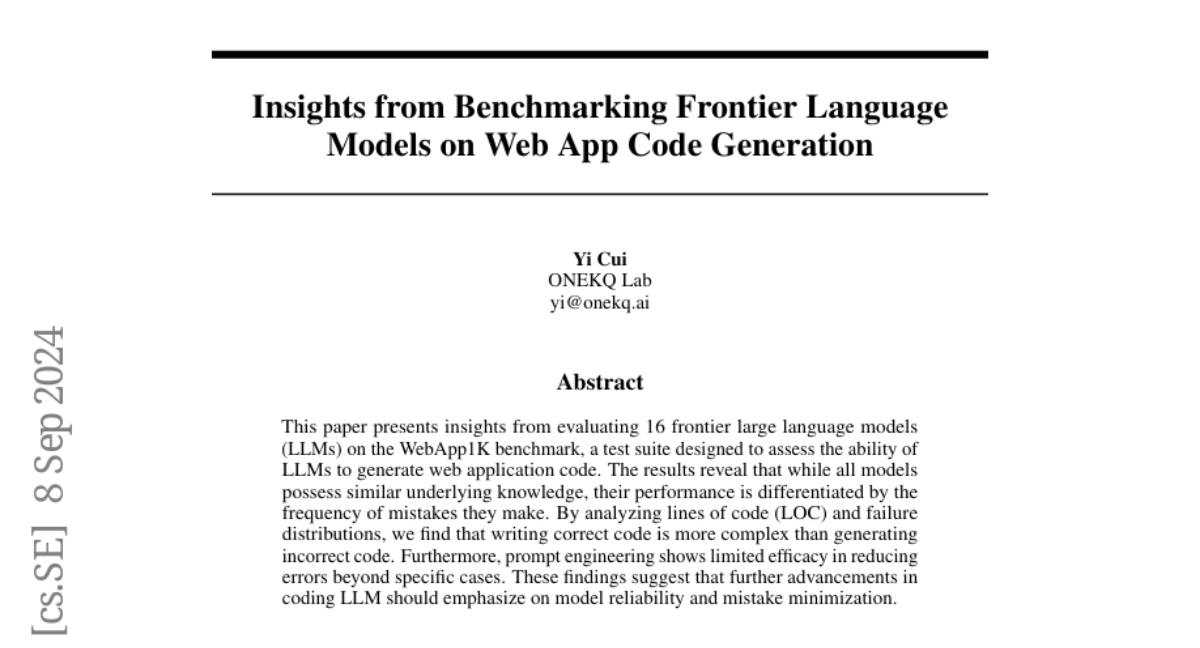
Papers
4
arxiv:
2505.09027
arxiv:
2409.13773
arxiv:
2409.05177
arxiv:
2408.00019
models
0
None public yet
datasets
0
None public yet