

MoJev


Typed, calibrated decisions in one forward pass.
Contact: contact@molemo.org
This is the trained checkpoint for the
mojev runtime. It scores
request-time candidate values from unstructured state and returns schema-bound
probability distributions.
| MoJev family resource | location |
|---|---|
| Code | MoLeMo-Lab/mojev |
| Model | MoLeMo-Lab/mojev |
| Dataset | MoLeMo-Lab/mojev-mix |
| Results | MoJev results |
| Preprint | MoJev (PDF) |
| Project page | MoJev |
Interactive demo
Try MoJev on Hugging Face Spaces: text, one or multiple images, a question, and custom candidates are scored on server-side ZeroGPU. No model weights are downloaded to the browser.
The optional browser/ text export uses asymmetric INT4 linear weights,
INT8 token embeddings, and an FP32 decision head. Export scripts and numerical comparisons are described in
the browser guide.
Model contract
| input | released configuration |
|---|---|
| state | text and local image references; 16,384-token training truncation |
| question | instruction text |
| candidates | request-time strings |
| output | logits decoded as Choice, Noul, or Score distributions |
Candidate names are supplied by the caller and encoded directly from their text.
MoJev's Qwen3.5 backbone supports 262,144 tokens natively and up to
1,010,000 tokens with YaRN scaling.
The checkpoint records the 16,384-token training window. The MoJev runtime
accepts a larger inference state window through --context-tokens; the packed
sequence also includes question and candidate tokens.
Run with the MoJev server
git clone https://github.com/MoLeMo-Lab/mojev
cd mojev
pip install -e '.[transformers]'

mojev serve MoLeMo-Lab/mojev --port 8000
For a longer state within the native context:
mojev serve MoLeMo-Lab/mojev --port 8000 --context-tokens 65536
from typesafe_sdk import Choice, TypeSafeClient

with TypeSafeClient(api_key="local", base_url="http://127.0.0.1:8000") as client:
    result = client.system_one(
        state={"document": "I was charged twice. Please fix this ASAP."},
        questions={
            "category": Choice(
                instructions="What is this ticket about?",
                criteria={"billing": None, "technical": None, "other": None},
            )
        },
    )

print(result.choices["category"].choice)
print(result.choices["category"].probabilities)
Load with Transformers
from transformers import AutoModel, AutoProcessor

model = AutoModel.from_pretrained(
    "MoLeMo-Lab/mojev",
    trust_remote_code=True,
).to("cuda").eval()
processor = AutoProcessor.from_pretrained(
    "MoLeMo-Lab/mojev",
    trust_remote_code=True,
)
The model directory contains the scorer implementation through auto_map.
Packing, candidate sorting, and schema decoding are provided by the
mojev package.
Multimodal input
pip install -e '.[transformers]'
mojev serve MoLeMo-Lab/mojev --port 8000
Use the image marker followed by an absolute path in the request state:
from pathlib import Path

image = Path("examples/cat.jpg").resolve()
state = f"Identify the subject. <|vision_start|><|image_pad|><|vision_end|>{image}"
The processor expands the image into visual patch tokens in the state branch. Every question and candidate in the request can attend to those tokens.
| candidate set | grey image P(cat) | cat image P(cat) |
|---|---|---|
cat, dog |
0.471 | 0.786 |
cat, dog, car, other |
0.264 | 0.528 |
Evaluation
On 12,000 evaluation decisions, the released checkpoint reaches 93.23% accuracy with 0.79% expected calibration error.
Architecture
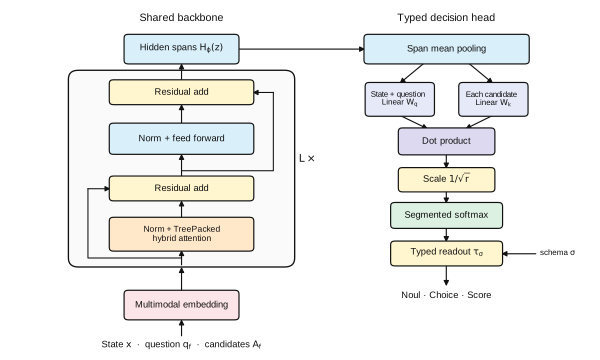
- Base: Qwen3.5-0.8B; all 854,036,544 parameters trained.
- Packing: state, questions, and candidates in one sequence.
- Attention: tree mask with isolated question/candidate branches.
- Readout: rank-512 context and candidate projections with scaled dot product.
- Objective: Plackett–Luce ranking plus Brier calibration loss.
- Precision: bf16 encoder and fp32 readout.
Training
| item | value |
|---|---|
| data | 205,084 rows from 18 Open-Jev generators |
| epochs | 1 |
| parallelism | 8-way data parallel |
| learning rate | 1e-5 |
| state truncation | 16,384 tokens |
| Brier weight | 1.0 |
| wall time | 47 minutes |
Applications
- routing and triage;
- policy and evidence classification;
- tool and workflow selection;
- calibrated execution, deferral, and escalation thresholds;
- multiple typed decisions over shared state.
Code is MIT licensed. The Qwen base model license applies to the checkpoint.
- Downloads last month
- 193
Model tree for MoLeMo-Lab/mojev
Dataset used to train MoLeMo-Lab/mojev
Spaces using MoLeMo-Lab/mojev 2
Evaluation results
- Accuracy on MoJev-Mix testtest set self-reported0.932