

Typed decisions, on your laptop, in one forward pass.


Send this model some state, a ticket or a record or a log line, plus questions with the answers you will accept. It returns a probability for every option you offered. It cannot answer with anything else, because it never generates text; it scores the options you gave it and stops.
Choicepicks one option from a list, with a probability for each.Noulmeasures whether a statement is true.Scoreplaces state on an ordered scale.- Confidence is calibrated, so a threshold means something.
596M parameters, about 1.2 GB. MLX on Apple Silicon, PyTorch everywhere else, fully offline.
Watch it decide
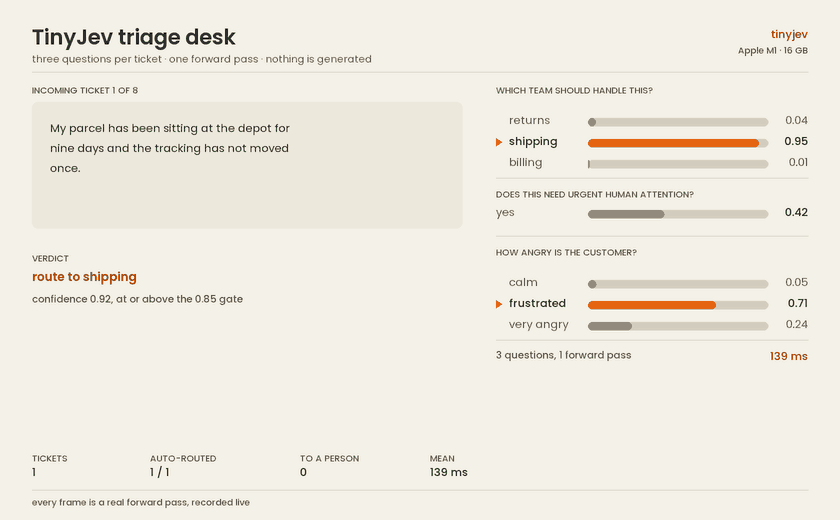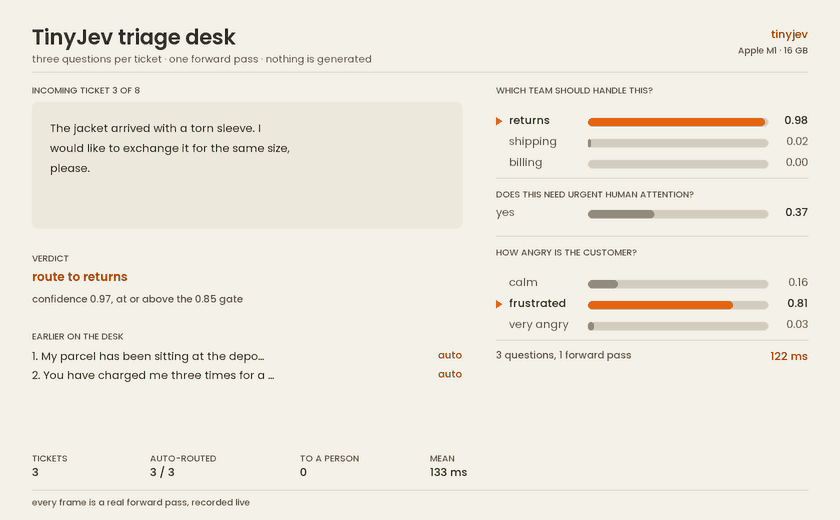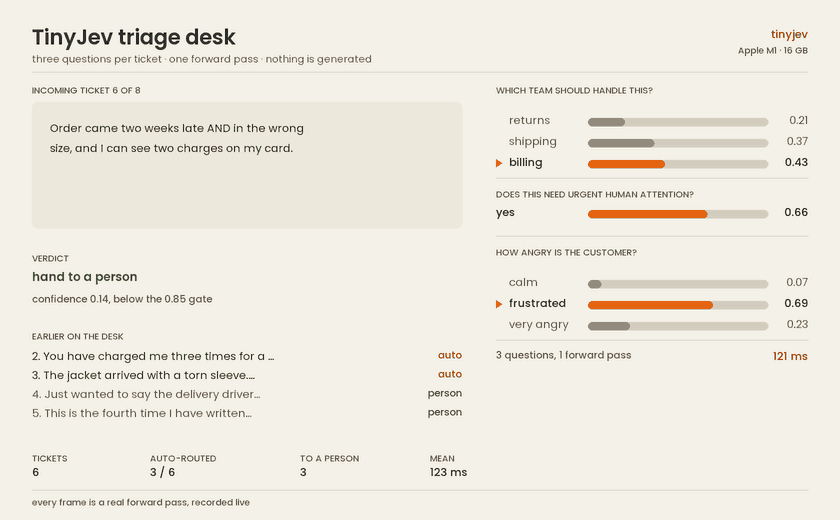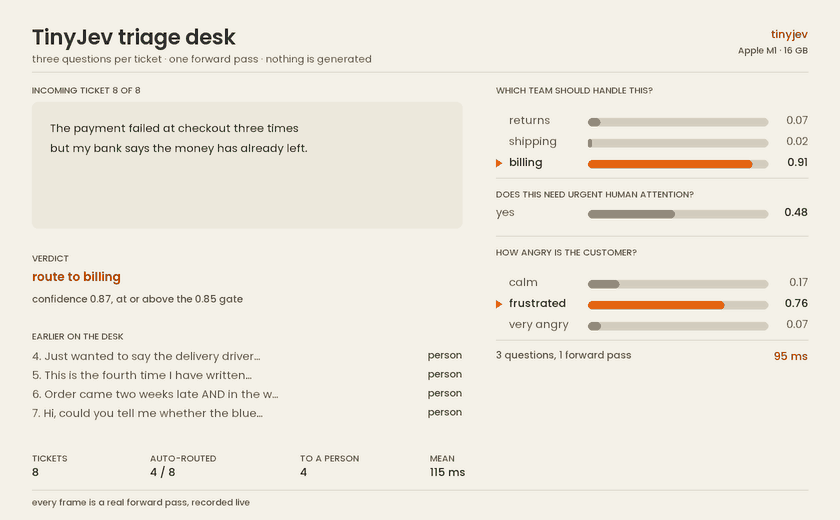
Eight real support tickets, three questions each in a single forward pass, about 110 ms per ticket on a base M1. Every number in that recording came from a live run.
Watch it play Doom
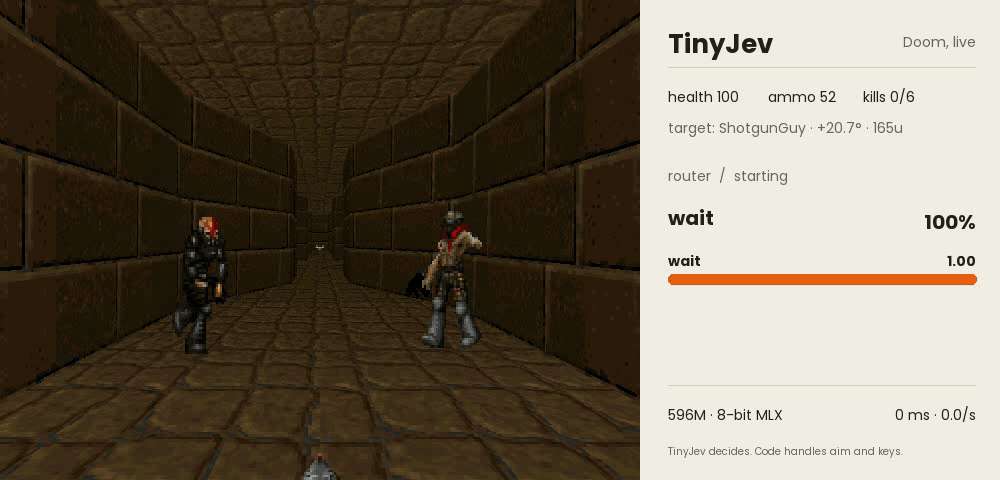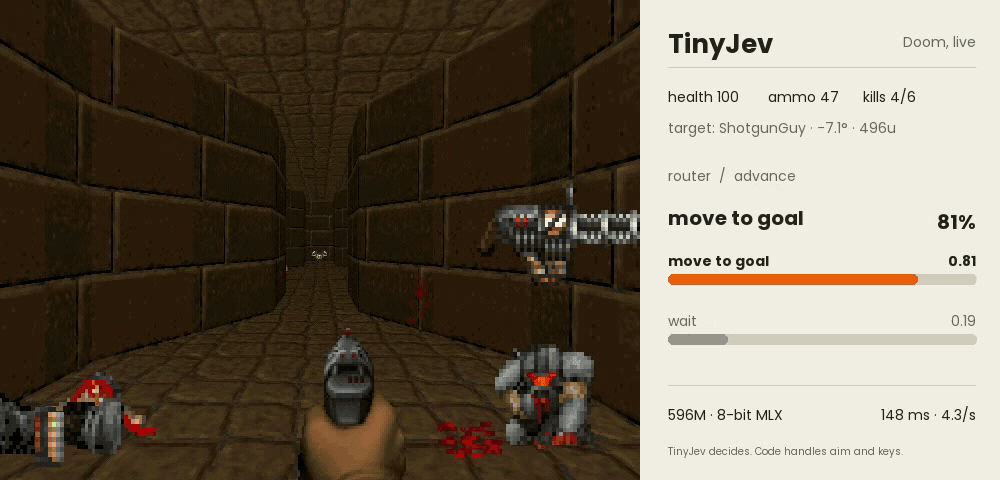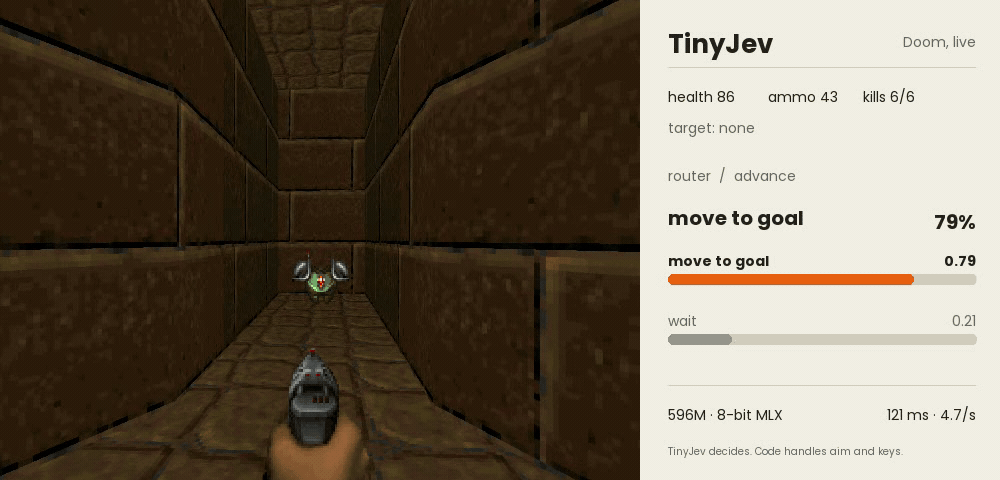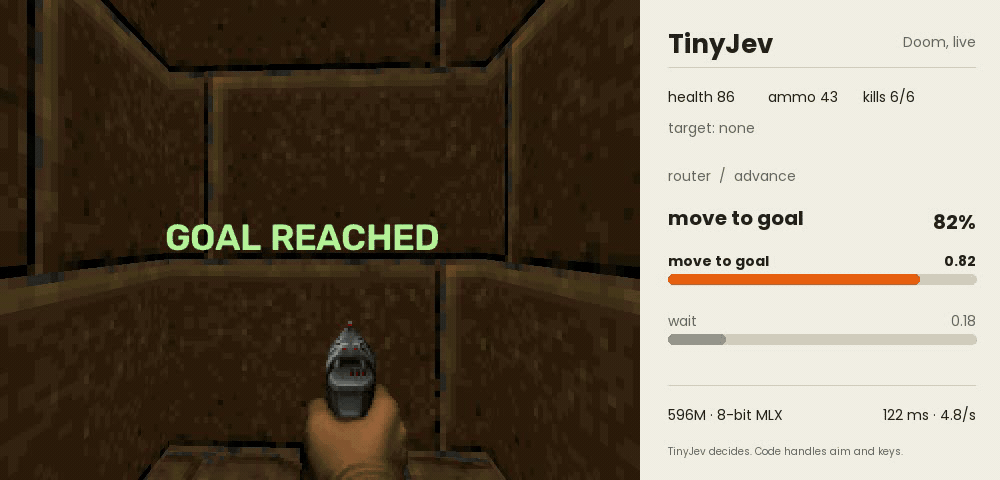
TinyJev is text-only, so it never sees the game pixels. VizDoom supplies health, ammo, enemy positions, recent damage and the location of the goal. A small rules-based router picks the tactical mode; TinyJev chooses a tactic and returns its probabilities; ordinary code handles aiming and key presses. In this fixed-seed run it kills all six enemies and reaches the goal.
pip install 'tinyjev[mlx,doom]'
python demos/doom_corridor.py --gif tinyjev_doom.gif
Use it
pip install 'tinyjev[mlx]'     # Apple Silicon
pip install 'tinyjev[torch]'   # everything else
import tinyjev
agent = tinyjev.load("tinyjev-0.6b")

agent.predict({
    "state": "Shoes arrived two weeks late and in the wrong size. Also I see two charges on my card.",
    "questions": {
        "team":     {"type": "choice", "instructions": "Which team should handle this?",
                     "criteria": {"returns": "Exchanges, refunds, wrong or damaged items",
                                  "shipping": "Delivery status, delays, lost packages",
                                  "billing":  "Charges, invoices, payment problems"}},
        "escalate": {"type": "noul",   "instructions": "Does this need urgent human attention?"},
        "anger":    {"type": "score",  "instructions": "How angry is the customer?",
                     "criteria": ["calm", "frustrated", "very angry"]},
    }})
On Apple Silicon you can quantize as it loads. Eight bits is free: half the memory, slightly faster, and it scored identically to full precision on our held-out set.
agent = tinyjev.load("tinyjev-0.6b", quantize=8)
Serve it over HTTP, speaking the System One request shape:
tinyjev serve tinyjev-0.6b # POST /v1/systemone on 127.0.0.1:8077
What is in this repo
AutoModel.from_pretrained("AnkitAI/tinyjev-0.6b") loads the backbone on its own, a standard
Qwen3Model in fp16. The decision head lives in head.safetensors, and tinyjev is what turns hidden
states into calibrated answers.
How it was built, and how it scores
Qwen3-0.6B-Base with a pointer head, LoRA r16 at lr 5e-5 merged back into the base, trained on the
public jaredpalmer/kev-suites decision-v7 split. No held-out transfer source was used in training.
A fitted temperature of 1.46 is applied at inference.
| transfer-v4 dev | transfer-v4 test, read once | ECE on test | |
|---|---|---|---|
| tinyjev-0.6b | 0.625 | 0.663 | 0.082 |
| Same-size public anchor | 0.620 | 0.642 | — |
Scored with the upstream harness on its frozen held-out suite. This matches the same-size public anchor and edges ahead on the locked test with lower calibration error. It is not 4B-class, and it is not meant to be. Full fine-tuning, distillation from a 4B teacher, and a 149M encoder were all tried and all lost to the configuration above.
tinyjev-0.6b is done and published. Next is a smaller one, around 0.15B.
Support the Project
If this model is useful in your work, you can support independent research:

Credits
Built on Qwen3-0.6B-Base (Apache-2.0). The training data, evaluation suites and the pointer-head design come from Kev by Jared Palmer (Apache-2.0). The typed-decision interface follows TypeSafe's Jev. MIT licensed.
- Downloads last month
- 65
Quantized
Model tree for AnkitAI/tinyjev-0.6b
Base model
Qwen/Qwen3-0.6B-Base